> ## Documentation Index
> Fetch the complete documentation index at: https://docs.growthbook.io/llms.txt
> Use this file to discover all available pages before exploring further.
# Setting Up Langfuse as an Event Tracker
> Tag Langfuse traces with GrowthBook assignments, connect the Langfuse ClickHouse database, and use latency, cost, token, and eval-score data as experiment metrics.
# Langfuse Event Tracker Setup
**Beta**
The Langfuse event tracker is in beta. It queries Langfuse's own ClickHouse database, which is not a stable API; re-validate the generated SQL after upgrading Langfuse.
[Langfuse](https://langfuse.com) is an open-source LLM observability tool. With this tracker, GrowthBook assigns the prompt or model variation and computes results, while Langfuse keeps recording what the model did and how well it scored. The end-to-end walkthrough, including prompt placement patterns and bandits, is in [Experimenting on LLM Features](/integrations/llm-tracing).
## Exposure Tracking
There is no separate exposure event. Instead, each Langfuse trace is tagged with the GrowthBook assignment in the form `gb.exp:=`, and the exposure query reads those tags straight from the `traces` table.
In JavaScript, the [`tracing` plugin](/lib/js#tracing) collects these tags for you. Attach them, together with the user id, at the top of the traced request:
```ts theme={null}
import { GrowthBook } from "@growthbook/growthbook";
import { tracingPlugin, getTracingTags } from "@growthbook/growthbook/plugins";
import { startActiveObservation, propagateAttributes } from "@langfuse/tracing";
const gb = new GrowthBook({
apiHost: "https://cdn.growthbook.io",
clientKey: "sdk-abc123",
attributes: { user_id: userId },
plugins: [tracingPlugin()],
});
await gb.init();
const promptLabel = gb.getFeatureValue("support-prompt", "production");
await startActiveObservation("support-reply", async () => {
await propagateAttributes({ userId, tags: getTracingTags(gb) }, async () => {
// ... fetch the prompt by label and call the model
});
});
```
Two things must hold for the join to work:
* The Langfuse `userId` (and `sessionId`, if used) must equal the value of the GrowthBook attribute the experiment hashes on.
* Experiment keys must not contain `=`.
Evaluate flags before starting the trace so the tags exist when it is created. For Python and plain OpenTelemetry examples, see [Stamping the trace](/integrations/llm-tracing#stamping-the-trace).
## Integrating with Langfuse Data
This tracker works with self-hosted Langfuse v3, which stores traces in ClickHouse.
* Connection type: **ClickHouse**, pointed at the Langfuse ClickHouse database that holds the `traces`, `observations`, and `scores` tables. Use a read-only ClickHouse user.
* Option `Langfuse project ID` — found in Langfuse under project settings. Leave blank to include every project in the database.
When you connect, GrowthBook generates:
* Identifier types `user_id`, `session_id`, and `trace_id`, with an exposure query for each and an identifier join between `user_id` and `session_id`. Exposure queries expose `trace_name`, `release`, and `version` as experiment dimensions.
* Fact table `Langfuse Traces` (one row per trace) with the metric **Traces per user**.
* Fact table `Langfuse Observations` (one row per generation, span, or event, with `latency_ms`, `time_to_first_token_ms`, token counts, `total_cost`, `model`, `prompt_name`, and `prompt_version`). Filters **LLM Generations** and **Errors**. Metrics **LLM calls per user**, **LLM cost per user**, **LLM error rate**, **p95 LLM latency**, and **Tokens per LLM call**.
* Fact table `Langfuse Scores` (one row per eval score, annotation, or piece of user feedback). `score_name` is an inline-filter column, so create a ratio metric (sum of `score_value` over a count of rows, both filtered by the score name) to get, for example, average helpfulness. See [Adding eval-score metrics](/integrations/llm-tracing#adding-eval-score-metrics). No score metrics are generated because score names are user-defined.
Caveats specific to Langfuse:
* **Langfuse Cloud** does not expose ClickHouse. Use Langfuse's [blob storage export](https://langfuse.com/docs/api-and-data-platform/features/blob-storage-export-fields) into your own warehouse and adapt the fact table SQL; the exported `observations` rows already include `user_id`, `session_id`, `tags`, `latency`, `total_cost`, and `usage_details`.
* **Langfuse v4** collapses these tables into a single `events` table. The generated SQL targets the v3 schema.
* The fact tables use `FINAL` to deduplicate ReplacingMergeTree rows. On very large installs replace it with `ORDER BY event_ts DESC LIMIT 1 BY id`.
* The `environment` column is omitted because older installs lack it; add it to the SQL by hand if you want it.
* Changing the project ID later in the data source settings does not rewrite SQL that was already generated.
## Configuration Settings
Once you have chosen your event tracker and data source type and successfully connected, you will be given an
opportunity to modify your configuration settings. For many applications GrowthBook will have chosen the correct
configuration settings straight out of the box based upon which event tracker you choose. In some instances you may need
to tweak them slightly, or in the case of using a custom datasource, define them more explicitly.
### Identifier Types
These are all the types of identifiers you use to split traffic in an experiment and track metric conversions. Common
examples are `user_id`, `anonymous_id`, `device_id`, and `ip_address`.
### Experiment Assignment Queries
An experiment assignment query returns which users were part of which experiment, what variation they saw, and when they
saw it. Each assignment query is tied to a single identifier type (defined above). You can also have multiple assignment
queries if you store that data in different tables, for example one from your email system and one from your back-end.
The end result of the query should return data like this:
| user\_id | timestamp | experiment\_id | variation\_id |
| - | - | - | - |
| 123 | 2021-08-23-10:53:04 | my-button-test | 0 |
| 456 | 2021-08-23 10:53:06 | my-button-test | 1 |
The above assumes the identifier type you are using is `user_id`. If you are using a different identifier, you would use a different column name.
Here's an example query you might use:
```sql theme={null}
SELECT
user_id,
received_at as timestamp,
experiment_id,
variation_id
FROM
events
WHERE
event_type = 'viewed experiment'
```
Make sure to return the exact column names that GrowthBook is expecting. If your table’s columns use a different name, add an alias in the SELECT list (e.g. `SELECT original_column as new_column`).
#### Duplicate Rows
If a user sees an experiment multiple times, you should return multiple rows in your assignment query, one for each time the user was exposed to the experiment.
This helps us detect when users were exposed to more than one variation, and eventually may be useful in helping build interesting time series.
#### Experiment Dimensions
In addition to the standard 4 columns above, you can also select additional dimension columns. For example, `browser` or `referrer`. These extra columns can be used to drill down into experiment results.
#### Identifier Join Tables
If you have multiple identifier types and want to be able to auto-merge them together during analysis, you also need to define identifier join tables. For example, if your experiment is assigned based on `device_id`, but the conversion metric only has a `user_id` column.
These queries are very simple and just need to return columns for each of the identifier types being joined. For example:
```sql theme={null}
SELECT user_id, device_id FROM logins
```
#### SQL Template Variables
Within your queries, there are several placeholder variables you can use. These will be replaced with strings before being run based on your experiment. This can be useful for giving hints to SQL optimization engines to improve query performance.
The variables are:
* **startDate** - `YYYY-MM-DD HH:mm:ss` of the earliest data that needs to be included
* **startYear** - Just the `YYYY` of the startDate
* **startMonth** - Just the `MM` of the startDate
* **startDay** - Just the `DD` of the startDate
* **startDateUnix** - Unix timestamp of the startDate (seconds since Jan 1, 1970)
* **endDate** - `YYYY-MM-DD HH:mm:ss` of the latest data that needs to be included
* **endYear** - Just the `YYYY` of the endDate
* **endMonth** - Just the `MM` of the endDate
* **endDay** - Just the `DD` of the endDate
* **endDateUnix** - Unix timestamp of the endDate (seconds since Jan 1, 1970)
* **experimentId** - Either a specific experiment id OR `%` if you should include all experiments
For example:
```sql theme={null}
SELECT
user_id,
anonymous_id,
received_at as timestamp,
experiment_id,
variation_id
FROM
experiment_viewed
WHERE
received_at BETWEEN '{{ startDate }}' AND '{{ endDate }}'
AND experiment_id LIKE '{{ experimentId }}'
```
**Note:** The inserted values do not have surrounding quotes, so you must add those yourself (e.g. use `'{{ startDate }}'` instead of just `{{ startDate }}`)
### Jupyter Notebook Query Runner
This setting is only required if you want to export experiment results as a Jupyter Notebook.
There is no one standard way to store credentials or run SQL queries from Jupyter notebooks, so GrowthBook lets you define your own Python function.
It needs to be called `runQuery`, accept a single string argument named `sql`, and return a pandas data frame.
Here's an example for a Postgres (or Redshift) data source:
```python theme={null}
import os
import psycopg2
import pandas as pd
from sqlalchemy import create_engine, text
# Use environment variables or similar for passwords!
password = os.getenv('POSTGRES_PW')
connStr = f'postgresql+psycopg2://user:{password}@localhost'
dbConnection = create_engine(connStr).connect();
def runQuery(sql):
return pd.read_sql(text(sql), dbConnection)
```
**Note:** This python source is stored as plain text in the database. Do not hard-code passwords or sensitive info. Use environment variables (shown above) or another credential store instead.
## Schema Browser
When you connect a supported data source to GrowthBook, we automatically generate metadata that is used by our Schema Browser. The Schema Browser is a user-friendly interface that makes writing queries easier as you can easily explore information about the datasource such as databases, schemas, tables, columns, and data types.
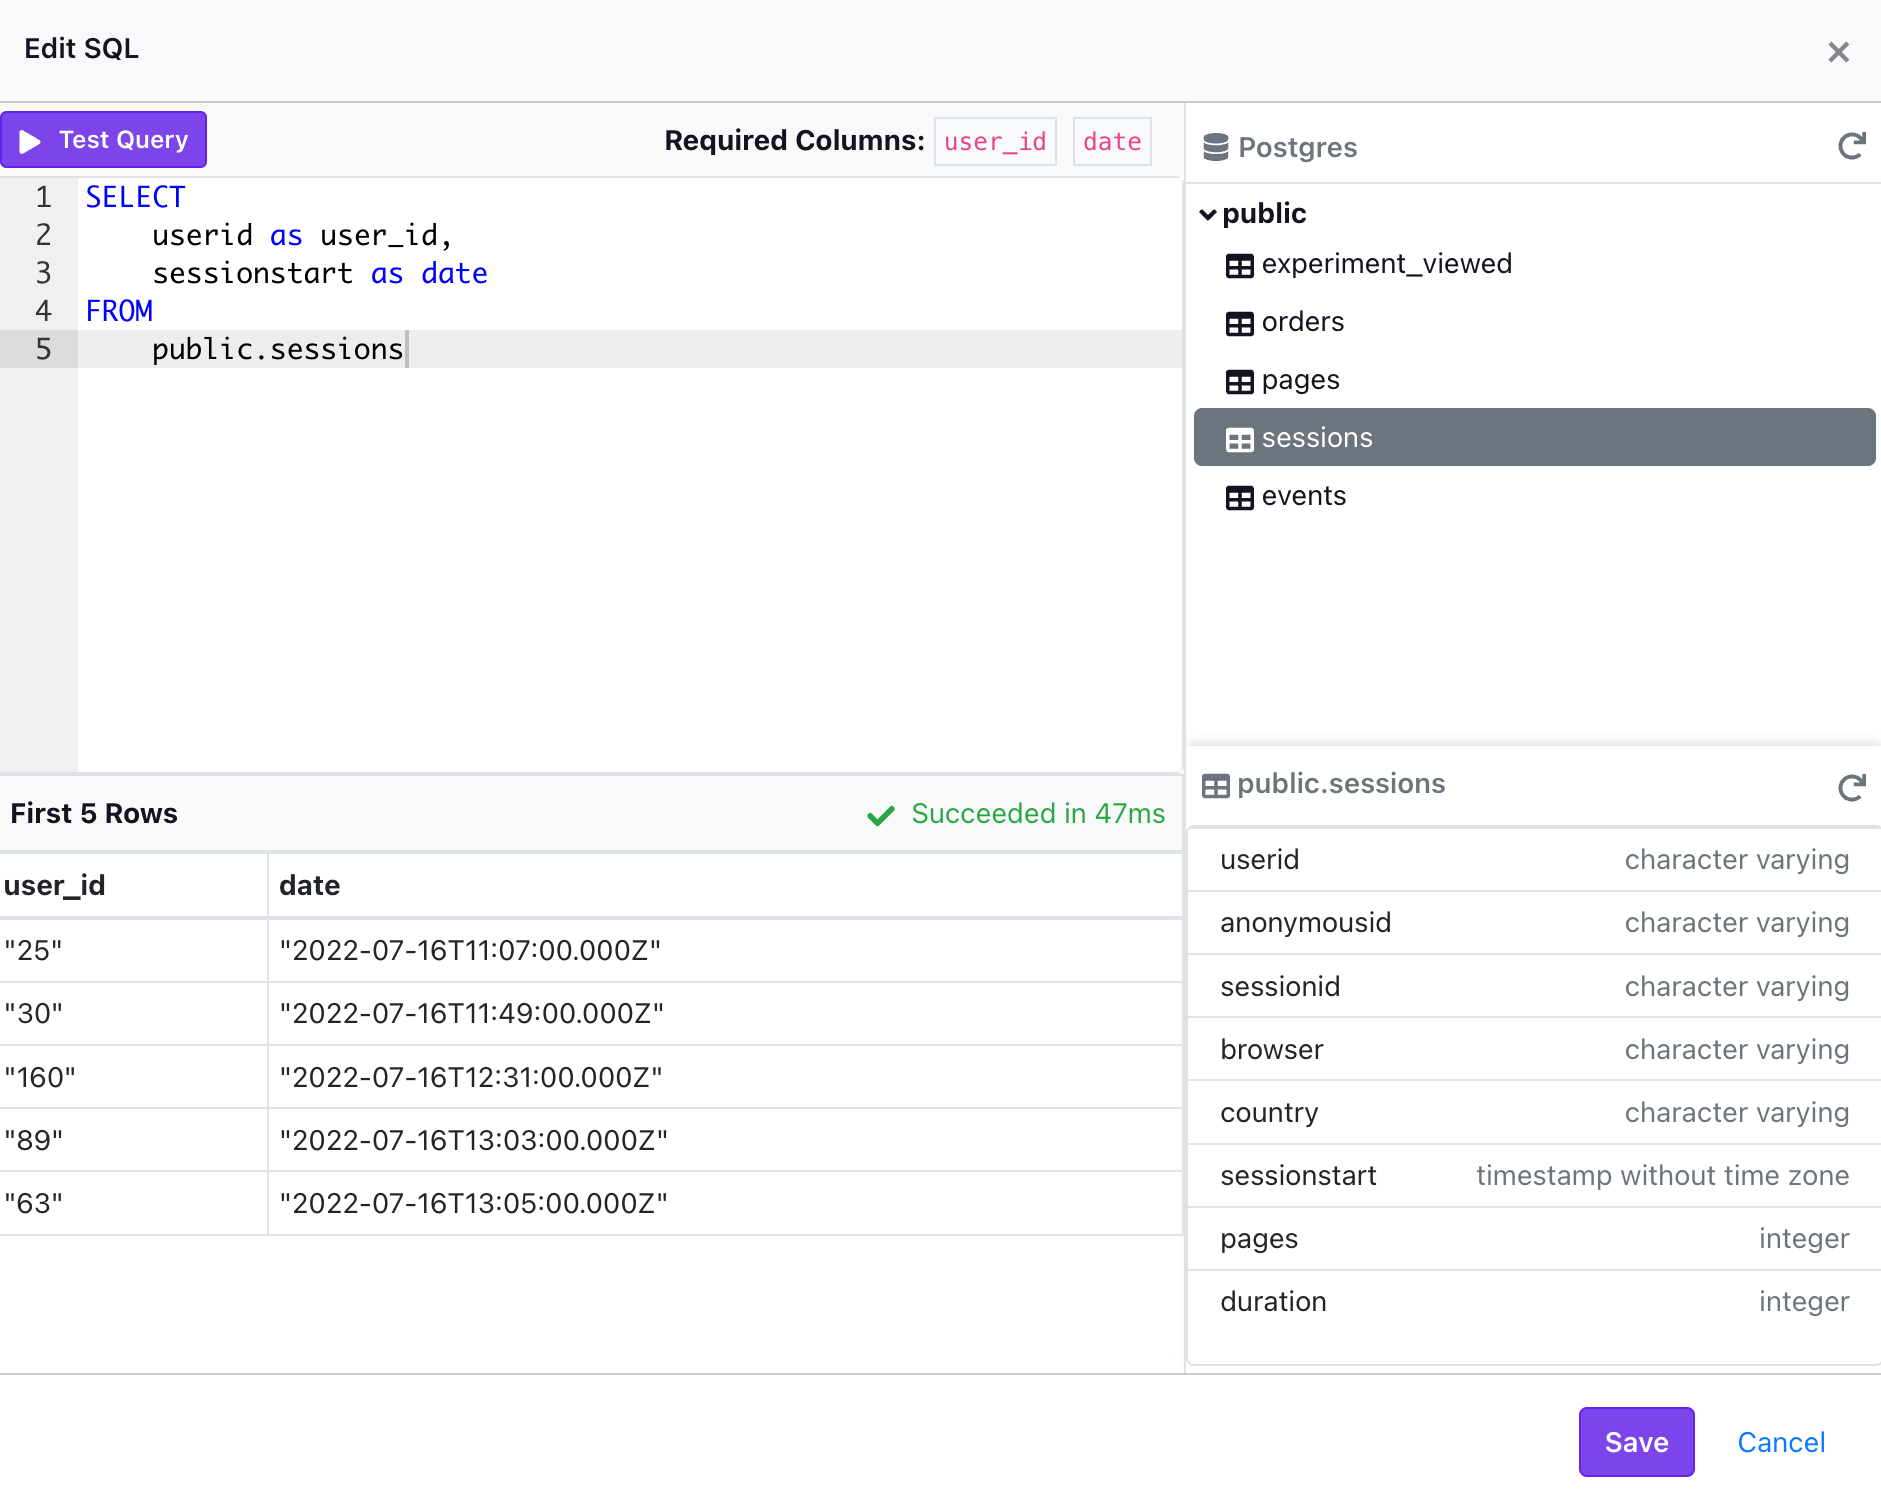 Below are the data sources that currently support the Schema Browser:
* AWS Athena - *Requires a Default Catalog*
* BigQuery - *Requires a Project Name and Default Dataset*
* ClickHouse
* Databricks - *Currently only supported on version 10.2 and above with a Unity Catalog*
* MsSQL/SQL Server
* MySQL/MariaDB
* Postgres
* PrestoDB (and Trino) - *Requires a Default Catalog*
* Redshift
* Snowflake