Paired analysis is the better powered tool when the engagement happens on the list itself, such as a click. Preference analysis is the one to use when the outcome is recorded somewhere that never sees the list, such as an order or booking, and when you want every user to count equally (see Airbnb’s blog post and paper for more details, which we largely follow here).
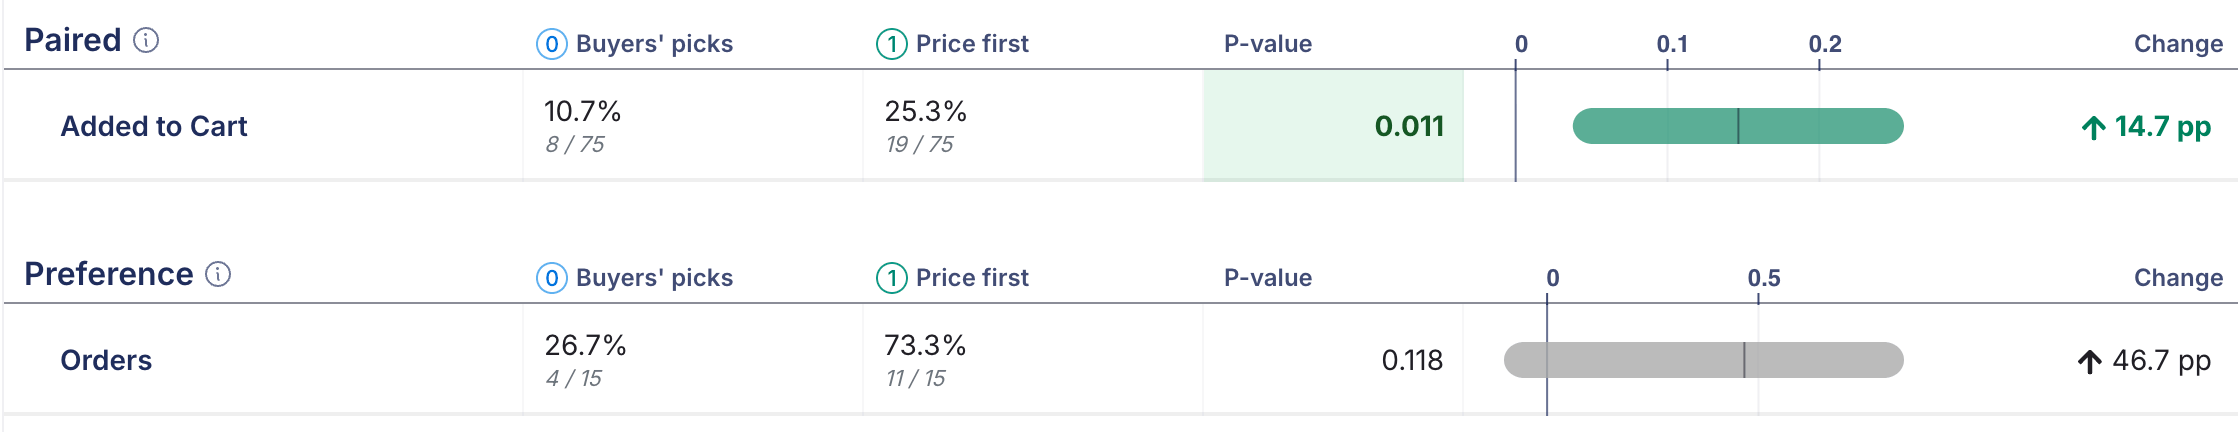
The Results tab shows one row per metric and analysis. Below “Added to Cart” is tracked with a paired analysis, and “Orders” is tracked with a preference analysis.
Paired analysis
Paired analysis compares the two rankers within each merged list. Every engagement with a competitive item credits the ranker that drafted it, so each impression yields a pair of credit totals, one per ranker. Only impressions where the user engaged with at least one competitive item matching the metric count, because an impression with no engagement says nothing about either ranker.
Attribution is fixed: an event joins to one impression through
ranking_id, and the ranker that drafted that item in that impression gets the credit. Events without a ranking_id, or with a timestamp before the impression’s, are not counted.
This is where most of interleaving’s speed comes from. Differences between users cancel out because both rankers are measured on the same impression, and only the items the rankers disagree on contribute. We recommend running paired analysis on at least one immediate engagement metric in every experiment.
Statistics: paired delta-method t-test
Statistics: paired delta-method t-test
For each user, sum over their engaged impressions the treatment credit , the control credit , and the number of competitive items the treatment drafted, (a fair draft gives the control the same number in expectation). The estimate is the difference in credited ratewith the variance from the delta method applied to the per-user triple . The term in that variance is the paired-design reduction: users who engage a lot do so with both rankers, and that shared variation cancels. The test is a two-sided t-test with degrees of freedom, and the confidence interval uses the same t quantile at your p-value threshold.Per-user sums are the unit, so a user who searches fifty times contributes fifty impressions to their sums. Very active users therefore carry more weight than in preference analysis.
Preference analysis
Preference analysis gives each exposed user one vote over the whole experiment, for the ranker whose items they engaged with more. Users who engaged with neither, or who gave both rankers equal credit, express no preference and are excluded from the test.Attribution
Preference analysis has a choice to make that paired analysis does not. An event carries anitem_id, but a user may have seen that item in several impressions, drafted by either ranker. The attribution setting on each preference analysis decides how the event’s credit is split between the rankers.
Exposure count is the same idea as Airbnb’s attribution of bookings to the ranker that championed the booked listing. Events count from the first time the user saw the item, and only competitive appearances count. Because attribution works from
item_id alone, preference analysis fits conversions recorded outside the list, such as a booking logged days later by another system.
You can add the same metric with more than one attribution, and each produces its own result row.
Statistics: exact binomial sign test
Statistics: exact binomial sign test
Each user with a preference reduces to a sign: treatment or control. With users preferring the treatment and preferring the control, the estimate is the net preference shareand the p-value is from an exact two-sided binomial test of against . The confidence interval is a Clopper-Pearson interval for , transformed to with your p-value threshold as the alpha. Tied users are excluded before the test; a tie is decided within a small numerical tolerance because fractional credit shares are not exact in floating point.
Which analysis for which metric
In general, we advise using Paired analysis whenever it makes sense to log a
ranking_id along with an event, and then combining that with Preference analysis whenever possible, to make sure they agree. Using a set of metrics in conjunction will likely lead to the best results.
Two further things to weigh:
- Heavy users. Paired analysis weighs users by how often they search; preference analysis gives everyone one vote. Pick the one that matches who you optimize for.
- Large values. Paired analysis on an amount, such as order value, lets a few large orders decide the result, as in a standard experiment. Preference analysis turns each user into one vote, so large values cannot dominate, but the difference between light and heavy users disappears.
Checks before you trust a run
- How often the rankers disagreed. Only competitive items count, so two rankers that mostly agree produce few comparisons, and a winner takes long to show and would change little for your users. Compare the number of users in the results with your traffic; a small share means the candidate may not be worth an A/B test slot. We have planned health checks to help you understand this component of interleaving experimentation.
- Engaged users. A significant paired result from a handful of engaged users is potentially fragile.
- Balance. The draft gives each ranker the same number of competitive items and the first pick in about half the rounds. If your exposure rows show otherwise, something between the SDK and the warehouse is reordering or dropping items. Again, we have planned health checks to automate this process.
How interleaving relates to A/B test results
When teams have run both on the same rankers, the two mostly point the same way, but not always. Airbnb compared 29 pairs and found the direction agreed 82% of the time. OTTO reports correlations between 0.47 and 0.68 depending on the outcome (Brinkmann and Wolle, 2025). The likely reasons for disagreement:- The merged list is a different choice set. No user ever sees either ranker alone. How much an attribute such as price weighs in a choice depends on the range of options on the page, so a ranker can win in the merge and do worse on its own. Airbnb saw a ranker that was neutral in an A/B test lose clearly in interleaving because the other ranker’s listings looked better next to it. Any ranker whose value lies in the whole list, such as diversity at the top of the page, is hard to measure this way.
- Credit ignores how far an item moved. Moving an item from position 4 to 3 earns the same credit as moving it from 50 to 3. An A/B test only notices the big move.
- Speed does not show. The merged list waits for the slower ranker, so a slow candidate can win without anyone noticing. Check latency in your own logs or in the A/B test on the finalists.
- Only users who engage are counted. Interleaving cannot tell whether a ranker makes more people engage at all, because nobody sees one ranker alone. An A/B test measures that directly.
- A winner, not an effect size. The size of the difference tells you how clear the preference is, not how much a business metric would move after shipping. In a marketplace, it also cannot show how supply shifts once the winner ships.
Limitations
- Frequentist analysis only. No CUPED, sequential testing, Bayesian results, or multiple-comparison corrections.
- No dimensions, metric capping, or conversion windows. Exposures and engagement are bounded by the experiment’s run windows.
- Paired analysis requires
ranking_idon engagement events. Attributing events without one to the user’s most recent matching impression is not available yet. - Exposure count is the only preference attribution. Engagement-signal attribution, which credits a conversion to the ranker that earned a separate signal event such as the click on the booked item, is planned.
- Furthermore, exposure count attribution currently uses all exposures, including those after the preference signal.